
Health insurance data does not stay static. Every new claim, policyholder, provider interaction, eligibility update, authorization, pharmacy transaction, and regulatory requirement adds to the amount and complexity of information an insurer must manage.
This is why scalability is a core requirement of health insurance data warehousing.
A scalable warehouse allows insurers to increase data volumes, onboard new sources, retain historical information, support more analytics users, and run increasingly complex workloads without repeatedly rebuilding the data environment.
A scalable warehouse allows insurers to increase data volumes, onboard new sources, retain historical information, support more analytics users, and run increasingly complex workloads without repeatedly rebuilding the data environment.
For health insurance data and analytics leaders, scalability is not simply about storing more records. It determines whether the data platform can continue supporting health insurance analytics, fraud detection, claims analysis, and regulatory reporting as business requirements grow.
Why Is Scalable Data Warehousing Important for Health Insurance Analytics?
Scalable data warehousing is critical because health insurers continuously accumulate claims, policyholder, provider, pharmacy, and operational data while analytical and regulatory demands also increase.
A scalable architecture allows insurers to:

- Process growing claims volumes
- Retain years of historical data
- Integrate additional source systems
- Support more analytics workloads
- Analyze larger populations
- Run fraud detection across broader datasets
- Handle regulatory reporting requirements
- Expand without repeatedly redesigning the warehouse
CMS provides a practical example at enterprise scale. Its Integrated Data Repository Cloud is a high-volume warehouse integrating Medicare claims with beneficiary, provider, contract, risk, and other data to support analytics and reporting.
Why Does Health Insurance Data Grow So Quickly?
Claims are only one part of a health insurer's data environment.
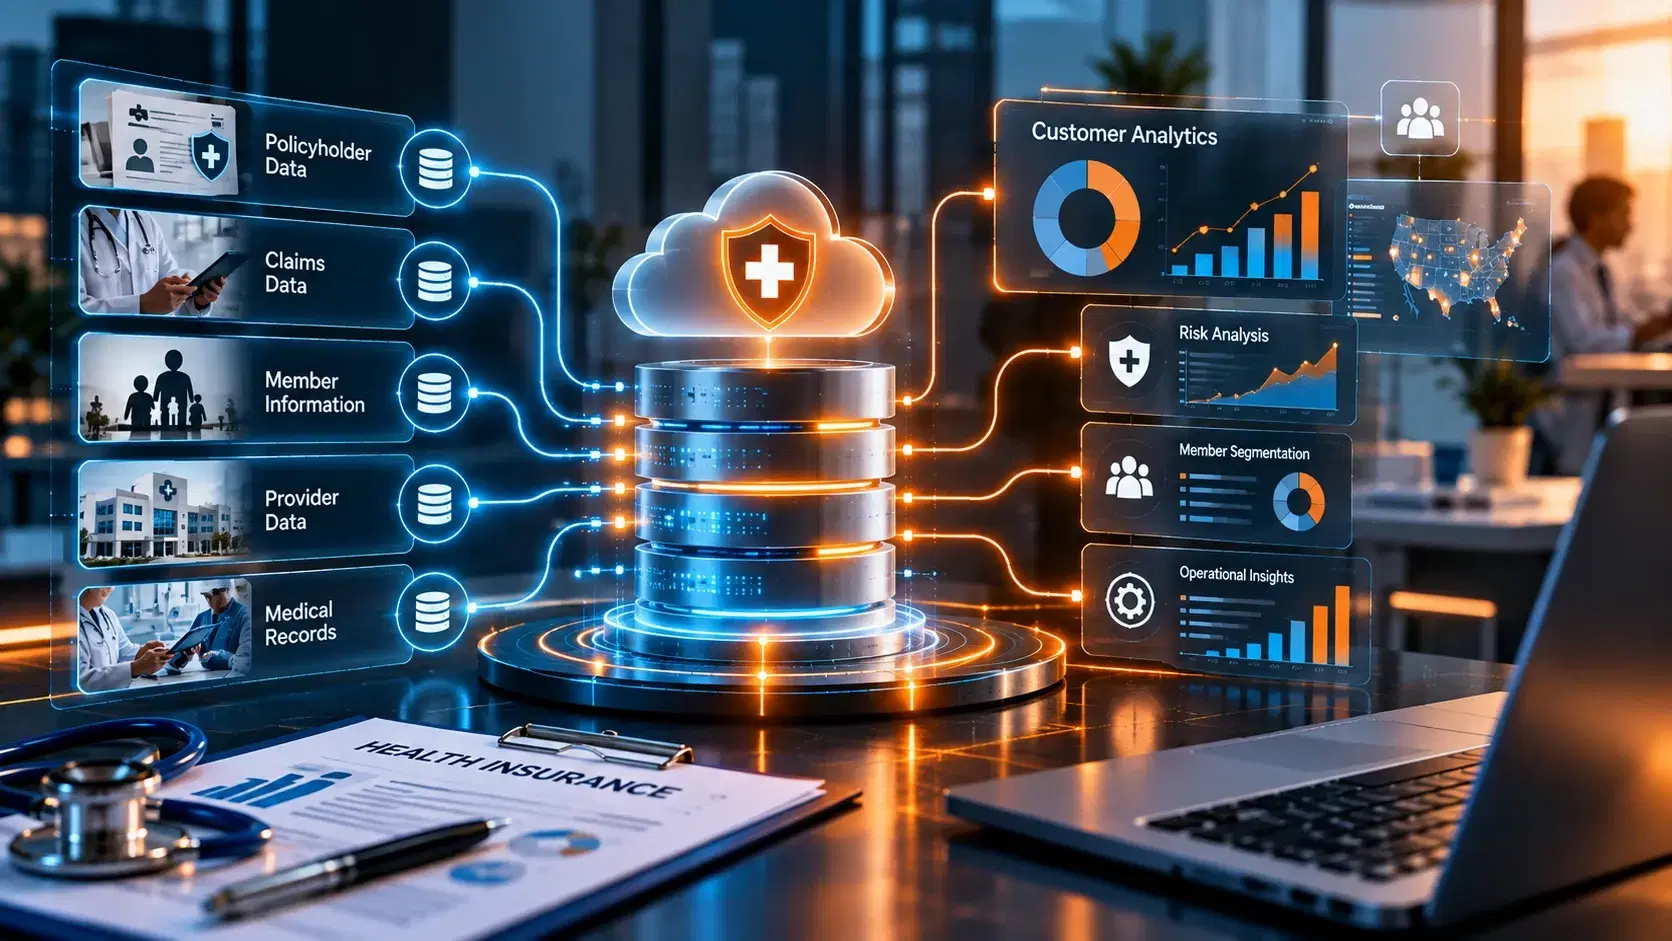
A warehouse may continuously receive information from:
Claims | Policyholders | Eligibility | Providers | Pharmacy | Authorizations | Finance | Customer Interactions | External Sources
A warehouse may continuously receive information from:
Claims | Policyholders | Eligibility | Providers | Pharmacy | Authorizations | Finance | Customer Interactions | External Sources
Growth also occurs in several dimensions at once.
An insurer may add more members, retain additional years of claims history, introduce new plans, connect new partners, increase reporting frequency, or introduce more detailed analytics.
For example, analyzing one year of summarized claims is very different from analyzing several years of claim-line history across millions of members.
A warehouse designed only around today's volume can eventually create performance problems, longer processing windows, and limitations on what analysts can investigate.
What Happens When a Health Insurance Data Warehouse Cannot Scale?
Scalability problems usually appear gradually.
A report that once took seconds may start taking minutes. Overnight data processing may continue into business hours. Analysts may receive only summarized data because detailed history has become difficult to query.
Eventually, teams can experience:
- • Slow dashboards and queries
- Longer claims-processing pipelines
- Delayed data availability
- Increasing infrastructure costs
- Limited historical analysis
- Difficulty onboarding new sources
- Competing workloads affecting performance
- Regulatory reports taking longer to prepare
The problem becomes particularly important when operational systems are used directly for analytics.
CMS architecture guidance separates high-volume transactional systems from analytical repositories because raw operational systems are not designed to serve analytical queries efficiently.
How Does Scalability Improve Claims Data Integration?
Claims data integration is rarely a one-time project.
Insurers may receive medical claims, pharmacy claims, adjustments, encounters, eligibility files, provider information, and external data through different formats and schedules.
Insurers may receive medical claims, pharmacy claims, adjustments, encounters, eligibility files, provider information, and external data through different formats and schedules.
These can include:
X12 | FHIR | APIs | Databases | Batch Files | Streaming Data
X12 | FHIR | APIs | Databases | Batch Files | Streaming Data
A scalable architecture allows new sources and increasing transaction volumes to enter the analytical environment without requiring every existing pipeline to be rebuilt.
This matters because claims data may arrive at different speeds.
Some feeds may run monthly or weekly. Others may need daily or near-real-time processing.
Some feeds may run monthly or weekly. Others may need daily or near-real-time processing.
CMS's Beneficiary Claims Data API, for example, provides standardized FHIR claims data and updates enrollee claims information at least weekly, illustrating how claims analytics increasingly depends on repeatable data integration rather than static extracts.
Why Does Historical Data Matter for Health Insurance Analytics?
One of the biggest reasons insurers need a scalable data warehouse is history.
A current claim tells analysts what happened today.
A current claim tells analysts what happened today.
Historical claims can reveal what is changing.
Consider a provider whose average monthly claim volume is normally 500 claims but suddenly rises significantly.
That change becomes meaningful only when current activity can be compared against historical behavior.
Long-term data can support:
Consider a provider whose average monthly claim volume is normally 500 claims but suddenly rises significantly.
That change becomes meaningful only when current activity can be compared against historical behavior.
Long-term data can support:
- • Claims trend analysis
- Cost changes over time
- Member utilization patterns
- Provider behavior analysis
- Plan performance
- Plan performance
- Population analysis
- Forecasting
- Fraud and anomaly analysis
A scalable warehouse should therefore make historical information usable rather than treating older data simply as archived storage.
How Does Scalability Support Fraud Detection?
Fraud detection depends heavily on patterns.
A suspicious transaction may not appear unusual when viewed independently. The signal may emerge only when it is compared with thousands or millions of historical claims.
A suspicious transaction may not appear unusual when viewed independently. The signal may emerge only when it is compared with thousands or millions of historical claims.
For example, analytics may investigate:
- Repeated claims for similar services
- Unusual billing frequency
- Unexpected provider-member patterns
- Abnormal utilization
- Duplicate or near-duplicate claims
- Sudden changes in billing behavior
As the number of claims and years of history increase, the amount of data that fraud models and analytical rules may need to evaluate also increases.
CMS's high-volume Integrated Data Repository supports program integrity activities involving fraud, waste, and abuse alongside utilization, cost, provider, and policy analytics.
CMS's high-volume Integrated Data Repository supports program integrity activities involving fraud, waste, and abuse alongside utilization, cost, provider, and policy analytics.
The warehouse itself does not determine whether fraud occurred. Its role is to provide sufficient integrated and historical data for analytical models, rules, and investigators to identify patterns worth reviewing.
Why Is Policyholder Data Consolidation Important for Scalability?
Claims become more useful when they can be connected to the correct member, plan, and coverage period.
However, policyholder data consolidation becomes increasingly difficult as the organization grows.
However, policyholder data consolidation becomes increasingly difficult as the organization grows.
One person may have:
- Multiple coverage periods
- Different policies over time
- Dependents
- Plan changes
- Employer-group changes
- Different identifiers across systems
Instead of repeatedly copying policyholder information into separate reporting datasets, a scalable warehouse can maintain reusable member and policy structures that support multiple analytical workloads.
This helps analytics teams examine claims in the correct coverage context while reducing unnecessary duplication.
CMS follows a similar integrated approach by bringing claims together with beneficiary, provider, plan, contract, and other information rather than treating each domain as an isolated analytical source.
CMS follows a similar integrated approach by bringing claims together with beneficiary, provider, plan, contract, and other information rather than treating each domain as an isolated analytical source.
How Does a Scalable Warehouse Improve Regulatory Reporting?
Regulatory reporting creates a different scalability challenge.
Requirements can change. New fields may be introduced. Reporting frequency can increase. Historical periods may need to be reproduced.
Requirements can change. New fields may be introduced. Reporting frequency can increase. Historical periods may need to be reproduced.
If every regulatory report depends on manually extracting information from operational systems, each new requirement creates additional work.
A warehouse provides a reusable reporting foundation where validated historical information can be retained and governed.
This allows teams to build a reporting path such as:
Source Data → Integration → Validation → Historical Warehouse → Reporting Rules → Regulatory Output
Source Data → Integration → Validation → Historical Warehouse → Reporting Rules → Regulatory Output
When requirements change, teams can modify controlled reporting logic rather than reconstructing the entire dataset from source systems.
What Does a Scalable Health Insurance Data Architecture Look Like?
A practical architecture separates different responsibilities:
Claims | Policyholders | Providers | Pharmacy | Authorizations | Finance
↓
Scalable Data Ingestion
Batch | API | X12 | FHIR | Streaming
↓
Processing & Standardization
↓
Data Quality & Reconciliation
↓
Historical Data Warehouse / Lakehouse
↓
Governed Business & Semantic Layer
↓
Health Insurance Analytics | Regulatory Reporting | Fraud Detection
Claims | Policyholders | Providers | Pharmacy | Authorizations | Finance
↓
Scalable Data Ingestion
Batch | API | X12 | FHIR | Streaming
↓
Processing & Standardization
↓
Data Quality & Reconciliation
↓
Historical Data Warehouse / Lakehouse
↓
Governed Business & Semantic Layer
↓
Health Insurance Analytics | Regulatory Reporting | Fraud Detection
This separation is important.
Data ingestion can scale as transaction volumes increase, storage can expand as history grows, and analytical processing can respond to changing workloads without forcing every component to scale in exactly the same way.
CMS's current IDR Cloud architecture similarly separates its data lake, ETL, and data warehouse components while supporting business intelligence, reporting, data sharing, and APIs.
What Should Scalable Data Warehouse Solutions Be Able to Handle?
Health insurance data leaders evaluating scalable data warehouse solutions should look beyond maximum storage capacity.
A scalable environment should be able to handle growth across several dimensions:
| Growth Area | What the Warehouse Should Support |
|---|---|
| Claims volume | Increasing transaction and claim-line records |
| Data history | Multiple years of detailed information |
| Source systems | New internal and external feeds |
| Users | More analysts, reports, and applications |
| Workloads | Reporting, analytics, fraud models, and data science |
| Frequency | Batch, daily, and near-real-time requirements |
| Regulations | New fields, rules, and reporting requirements |
AWS's current payer architecture, for example, describes ingestion across claims, provider, clinical, and other sources using formats such as X12 and FHIR, with different purpose-built stores and analytical services depending on the workload.
This illustrates an important principle: scalability is not only about making one database larger. It is about designing the overall data architecture so different workloads can grow appropriately.
This illustrates an important principle: scalability is not only about making one database larger. It is about designing the overall data architecture so different workloads can grow appropriately.
For implementation guidance, teams often evaluate data engineering best practices and consider data lake consulting when integrating large, varied health data sources.
How Can Health Insurance Data Leaders Test Scalability?
Instead of asking only, “How much data can this platform store?”, ask questions based on future business conditions:
What happens when claims volume doubles?
Can we retain detailed claim history without slowing current reporting?
Can a new source system be added without rebuilding existing analytics?
Can fraud models and executive dashboards run at the same time?
Can we reproduce a regulatory report using historical data?
Can additional analytics teams use the platform without creating separate copies of the same data?
Can processing capacity grow independently when workload demand increases?
What happens when claims volume doubles?
Can we retain detailed claim history without slowing current reporting?
Can a new source system be added without rebuilding existing analytics?
Can fraud models and executive dashboards run at the same time?
Can we reproduce a regulatory report using historical data?
Can additional analytics teams use the platform without creating separate copies of the same data?
Can processing capacity grow independently when workload demand increases?
These questions test whether scalability exists at the architectural level rather than only in product specifications.
Teams should also look at data modernization strategies and data warehousing consulting resources to validate vendor claims with proven architectural patterns and migration approaches.
Key Takeaway
Scalability in health insurance data warehousing is not simply about preparing for more storage.
Health insurers need to accommodate growing claims volumes, longer histories, additional source systems, more analytics users, evolving regulatory reporting, and increasingly sophisticated fraud detection.
A scalable architecture gives insurers room to expand these workloads without continually rebuilding the data foundation.
For health insurance analytics, the real measure of scalability is whether the warehouse can handle tomorrow's data and questions while continuing to make today's information accessible, reliable, and useful.
Health insurers need to accommodate growing claims volumes, longer histories, additional source systems, more analytics users, evolving regulatory reporting, and increasingly sophisticated fraud detection.
A scalable architecture gives insurers room to expand these workloads without continually rebuilding the data foundation.
For health insurance analytics, the real measure of scalability is whether the warehouse can handle tomorrow's data and questions while continuing to make today's information accessible, reliable, and useful.
Build a data foundation that can grow with your claims, analytics, and reporting needs without adding unnecessary complexity.